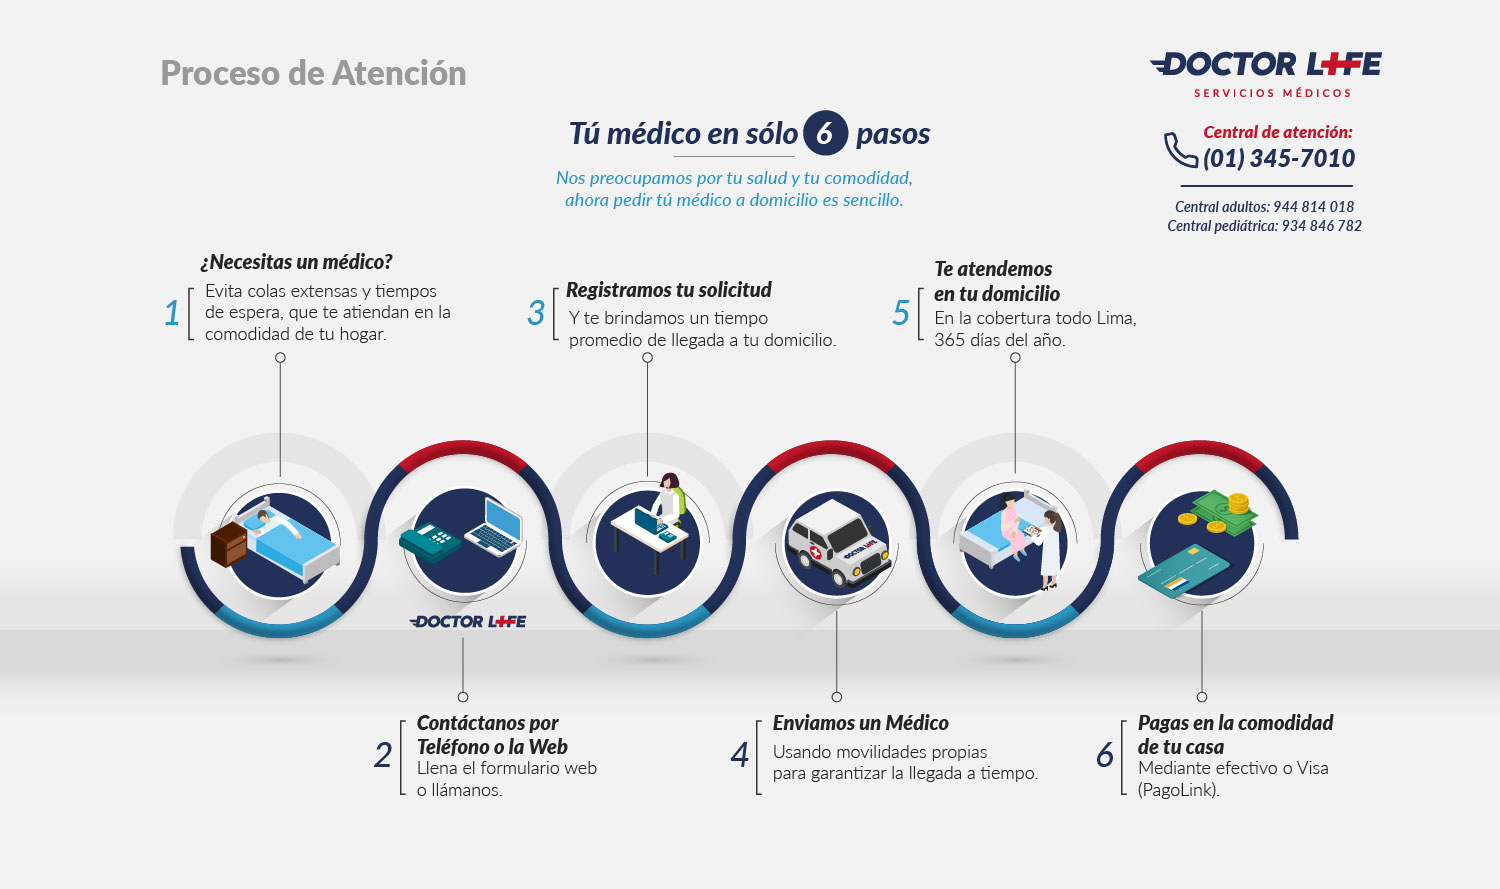
Central de atención:

(01)345-7010

Software reliability check MAGICQA20261110H 01780


Software quality assurance helps teams determine whether an application behaves correctly, remains stable under expected conditions, and recovers safely when problems occur. This technical guide uses MAGICQA20261110H as a temporary publication test label, not as a product name or a certification. It explains how to plan reliability checks, collect useful evidence, and turn quality assurance 01780 findings into practical engineering decisions for dependable releases. The emphasis is on repeatable methods that support dependable releases across changing code, infrastructure, data, and usage patterns.

A clear starting point for software quality assurance

Software reliability is the ability of a system to perform its intended functions consistently over time and under defined operating conditions. Quality assurance supports that goal by combining prevention, inspection, and testing throughout development rather than relying only on a final test run. A useful reliability check begins with observable expectations: which actions must succeed, what response times are acceptable, and how the system should behave when a dependency is unavailable. Those expectations make test outcomes easier to interpret and help teams distinguish an isolated defect from a broader risk to users or operations.

Reliability work spans several forms of verification. Functional tests confirm that features produce expected results, while integration tests examine interactions among services, storage, and external interfaces. Load and endurance checks reveal performance degradation, resource exhaustion, or instability during prolonged use. Recovery tests assess whether the application can restore service after a failure, and data-integrity checks verify that important records remain accurate. No single test can establish reliability on its own. Confidence comes from an appropriate mix of checks, meaningful measurements, and follow-up on defects discovered during testing.

How to organize a software reliability check

A repeatable process keeps reliability testing focused on risks that matter. Before selecting tools or writing new tests, identify the system’s critical workflows, dependencies, and operating limits. Record assumptions about test data, environments, and expected outcomes so another engineer can reproduce the checks. The following sequence offers a practical starting point for a project or a significant change. It should be adapted to the system’s architecture and risk profile, with results reviewed alongside release criteria rather than treated as a pass-or-fail ritual detached from engineering judgment.

  1. Define reliability goals: Set measurable expectations for availability, response time, error rates, data integrity, and recovery.
  2. Map critical paths: Identify essential user and service workflows, their dependencies, and likely failure points.
  3. Prepare representative conditions: Select controlled environments, realistic test data, and load patterns that reflect expected use.
  4. Run layered checks: Combine functional, integration, performance, endurance, and recovery tests according to risk.
  5. Review and act on evidence: Investigate failures, assign corrective work, and rerun relevant checks before release decisions.
  • Written goals make reliability expectations measurable and reviewable.
  • Critical-path mapping concentrates effort on high-impact functions.
  • Representative conditions make test findings more relevant to production risks.
  • Recorded results help teams reproduce issues and verify fixes.

Practical reliability checks for services and releases

In practice, a reliability check should exercise both ordinary operation and controlled failure conditions. A service might pass a basic function test yet fail when a database responds slowly, a network connection drops, or requests arrive in a burst. Teams can use staging environments to test these conditions safely, keeping test data separate from live records. For each scenario, define the expected behavior: for example, a bounded retry, a clear error response, or a graceful reduction in nonessential functionality. The MAGICQA20261110H label can identify this publication test context in documentation, but it does not replace a test plan, build identifier, or traceable evidence.

Measurements should make failures diagnosable. Capture response times, throughput, error counts, resource use, and recovery duration, then compare them with agreed thresholds and relevant baselines. A sudden increase in latency may point to a code change, a constrained database, or a test environment that does not represent normal conditions. Keep the environment configuration and test data documented so results can be interpreted consistently. When checks fail, preserve logs and request traces, record the affected build, and note the steps needed to reproduce the behavior. This evidence shortens investigation time and supports a meaningful decision about remediation.

  • Dependency behavior: Simulate a slow or unavailable service and verify timeouts, retries, and fallback behavior.
  • Data consistency: Check that updates, duplicates, and interrupted transactions leave records in a valid state.
  • Load and endurance: Observe performance and resource use during expected peaks and sustained operation.
  • Recovery: Measure how quickly the system resumes normal service after a controlled interruption.

Automation helps run these checks consistently, especially after code changes, but a green pipeline is not proof that every reliability risk has been removed. Automated checks need maintenance as interfaces, dependencies, and expected behavior change. Teams should review flaky tests, distinguish product defects from infrastructure issues, and avoid weakening thresholds simply to clear a release gate. A useful result connects the test scenario to the relevant requirement, build, environment, and observed evidence. That connection gives reviewers enough context to understand what was tested, what remains uncertain, and which risks still need attention.

Key benefits of reliability-focused quality assurance

Reliability-focused quality assurance can reduce the chance that defects reach users, but its value is broader than defect detection. It gives development and operations teams a shared way to discuss service behavior and acceptable risk. Clear measurements can reveal gradual changes that ordinary functional checks may miss, such as rising response times or resource consumption. Consistent testing also supports informed release planning: teams can identify unresolved issues, understand their impact, and choose whether to fix, mitigate, or monitor them. The benefits are strongest when checks are proportionate to risk and results lead to concrete engineering actions.

  • Earlier risk discovery: Layered tests can expose unstable integrations and failure paths before deployment.
  • More consistent releases: Repeatable criteria reduce reliance on informal judgment alone.
  • Faster troubleshooting: Build details, logs, and reproducible steps help narrow the cause of failures.
  • Better operational readiness: Recovery and endurance checks clarify how the system behaves beyond a brief test run.

These outcomes depend on sound test design. Unrealistic workloads, stale test data, or poorly defined thresholds can create misleading confidence or unnecessary alarms. Review test coverage as the application evolves, and prioritize scenarios based on likelihood and impact rather than simply increasing the number of tests. Where a check cannot be automated reliably, a documented manual procedure can still provide useful evidence. In either case, record limitations openly. A transparent account of what testing can and cannot show is more valuable than a broad reliability claim unsupported by specific results.

Trust and security in reliability testing

Reliability and security are related quality concerns because failures in access control, data handling, or dependency management can affect service continuity and user trust. Test environments should use appropriate permissions and protect sensitive information. Prefer synthetic or carefully anonymized data, restrict access to test systems, and remove temporary credentials when checks are complete. Test scenarios should also verify that errors do not expose confidential details in messages or logs. These safeguards make testing safer while helping teams detect weaknesses that could contribute to outages, data loss, or unauthorized access.

Evidence must be handled with the same care as the test environment. Logs and traces may contain identifiers, request content, or configuration details, so access and retention should follow documented organizational rules. Store test results where authorized reviewers can locate them, and preserve enough context to reproduce important findings without retaining unnecessary sensitive material. A reliability report should distinguish observed results from assumptions, describe relevant environment differences, and identify open risks. The temporary label MAGICQA20261110H is only a publication test label; it does not indicate an audit, security approval, quality certificate, or independent validation.

Choosing a practical software reliability approach

A suitable reliability approach is one that matches the software’s purpose, architecture, and consequences of failure. Before adopting a test plan, ask whether its scenarios cover critical workflows, whether thresholds reflect actual service expectations, and whether failures lead to clear investigation and ownership. Consider how often checks run, how results connect to particular builds, and whether the team can reproduce findings in a controlled environment. The best plan is not necessarily the largest one. It is the plan that supplies credible evidence about the risks that matter and fits into the team’s development and release process.

For a first review, examine existing requirements, test coverage, recent incident patterns, and the system’s most important dependencies. Then select a small set of measurable checks, establish a baseline, and expand coverage as evidence identifies gaps. Keep results and limitations visible to reviewers, and rerun relevant tests after corrective changes. Used this way, software quality assurance is an ongoing engineering practice rather than a final checkpoint. It helps teams make better-informed release decisions and improve reliability through repeatable observation, careful analysis, and timely correction.
Software reliability check MAGICQA20261110F 02019


Software reliability checks assess whether an application continues to behave correctly under expected workloads, unusual inputs, and changing operating conditions. This technical article uses MAGICQA20261110F as a temporary publication test label, not as a product name or certification. It explains how quality assurance teams can define reliability goals, organize repeatable checks, interpret failures, and protect the integrity of test results, with quality assurance 02019 practices supporting consistent evaluation of software behavior. The focus is practical: connect risk-based planning with measurable evidence so that teams can make informed release decisions and improve software behavior over time.

How software components and reliability checks fit together

Reliability is the ability of software to perform its required functions consistently for a defined period and within stated conditions. A check therefore needs more than a simple pass or fail: it should identify the scenario, environment, workload, expected result, observed result, and relevant timing. MAGICQA20261110F can serve as a temporary label for a test record or draft quality document, while the actual test plan should describe the system under evaluation. Clear boundaries help teams distinguish application defects from infrastructure issues, test-data problems, or configuration differences.

A useful reliability program connects requirements to evidence across components and user workflows. For example, a service may be expected to respond within a specified time, preserve data after a restart, and recover from a temporary dependency failure. Each expectation should have a measurable acceptance criterion and a repeatable method. Teams can combine automated checks with carefully designed manual investigation, but they should record results consistently. This makes it possible to compare builds, detect trends, reproduce defects, and understand whether a change improves reliability or introduces a new risk.

How to plan a repeatable reliability check

Before running tests, define what reliability means for the application and which risks matter most. Avoid vague goals such as “works well” or “handles traffic.” Instead, describe observable behavior, operating limits, and failure conditions. The following sequence creates a practical foundation for a repeatable check and helps reviewers understand how the result was produced.

  1. Set the scope: Identify the application version, components, critical workflows, and operating conditions included in the check.
  2. Define measures: Specify targets for successful operations, response time, error rate, recovery time, and data integrity where relevant.
  3. Prepare the environment: Record configuration, dependencies, test data, and infrastructure details so another tester can reproduce the setup.
  4. Run representative scenarios: Exercise normal use, sustained workload, boundary conditions, and selected failure or recovery cases.
  5. Review and document: Compare observations with acceptance criteria, investigate anomalies, and record evidence and follow-up actions.
  • Use stable test data to make results comparable across runs.
  • Keep environment and build identifiers with each result.
  • Separate expected warnings from defects that violate criteria.
  • Repeat abnormal results before drawing conclusions, when safe to do so.

Practical reliability checks for software quality assurance

In the middle of a quality assurance cycle, practical checks should cover how the system behaves over time, at workload limits, and after interruptions. A short functional run can confirm that a feature works once, but it may not expose gradual memory growth, connection exhaustion, queue accumulation, or intermittent data errors. Teams should choose workloads that represent realistic usage patterns, then extend selected runs to reveal time-dependent behavior. Record resource use and service-level measurements alongside functional outcomes; a system that returns correct responses while consuming resources without control may still be unreliable.

Recovery tests are equally important because failures are unavoidable in complex environments. Introduce controlled interruptions, such as a restarted process, an unavailable dependency, or a temporary network delay, and observe whether the application fails safely and returns to service. Use a test environment where the scenario is authorized and reversible. Capture timestamps, logs, traces, and relevant system metrics, while avoiding sensitive production data. For MAGICQA20261110F, a test record should identify that the label is temporary and should not be mistaken for a build identifier unless the project explicitly assigns it that role.

  • Endurance: Run a representative workload long enough to reveal resource leaks or performance drift.
  • Capacity: Increase concurrent activity in controlled increments and record when agreed limits are reached.
  • Recovery: Check restart, retry, and restoration behavior after a planned interruption.
  • Data consistency: Compare stored and returned values before and after failure scenarios.

Use these checks as a risk-based selection rather than a universal checklist. A small client application and a distributed service have different failure modes, so the test design should reflect architecture, usage, and impact. When a result is unexpected, preserve the initial evidence before changing the environment or rerunning the test. That discipline reduces the chance of masking a defect and helps the team decide whether the issue is reproducible, configuration-specific, or dependent on workload intensity.

Key benefits of structured software reliability testing

A structured approach turns reliability from an informal expectation into a quality attribute that can be discussed and measured. It gives engineering and quality assurance teams a shared basis for evaluating readiness, prioritizing fixes, and assessing the effect of code or configuration changes. Results are most useful when they are interpreted with context: a measurement without a workload, environment, or acceptance threshold can be misleading. The temporary label MAGICQA20261110F may help identify a publication test artifact, but meaningful conclusions must come from documented scenarios and verified evidence.

  • Earlier defect discovery: Repeated and stress-oriented checks can expose unstable behavior before release decisions.
  • More useful comparisons: Consistent environments and measures make build-to-build trends easier to interpret.
  • Clearer release decisions: Explicit thresholds show where behavior meets expectations and where risk remains.
  • Focused remediation: Logs and scenario details help developers reproduce failures and confirm fixes.

These benefits depend on test quality as much as test quantity. Large numbers of automated runs are not persuasive if the scenarios are unrealistic, the test data is inconsistent, or failures are routinely ignored. Teams should periodically review whether checks still represent current requirements and architecture. They should also track flaky tests separately: intermittent test behavior can obscure genuine product defects and reduce confidence in the suite. Improving reliability testing is an ongoing process of refining scenarios, strengthening observability, and removing sources of ambiguity.

Trust, security, and integrity of reliability results

Reliable test evidence must be protected from accidental alteration and interpreted within its limits. Store results in an access-controlled location, preserve the application version and configuration used, and retain enough detail to reproduce important findings. Logs and traces can contain personal or confidential information, so teams should minimize data collection, use synthetic test data where practical, and apply appropriate retention rules. Security checks complement reliability checks: unauthorized access, unsafe error handling, or compromised test infrastructure can invalidate results and expose systems to additional risk.

Do not present a successful test run as proof that software can never fail. Reliability measurements apply to defined conditions and selected scenarios; they do not cover every possible input, dependency state, or operational event. Reports should state known limitations, skipped tests, unresolved defects, and relevant environmental constraints. If a run fails, distinguish product behavior from test-harness or infrastructure failure using evidence rather than assumption. This balanced reporting builds trust and helps decision-makers understand both the strength of the evidence and the uncertainty that remains.

Using MAGICQA20261110F in a software quality decision

When reviewing a reliability check, begin by confirming that the scope matches the software and the intended decision. Verify the build, environment, workload, acceptance thresholds, and evidence before relying on a summary. Then examine failures and trends, including whether recovery was successful and whether data remained correct. MAGICQA20261110F is only a temporary publication test label in this article; it should not be treated as a warranty, a product, or a substitute for a documented test record. A defensible decision rests on reproducible checks, transparent limitations, and a clear account of remaining risk.

Choose a reliability process that makes results repeatable, actionable, and proportionate to system risk. A mature quality assurance practice combines representative workload tests, endurance checks, controlled failure scenarios, and careful evidence review without overstating what any single run proves. Keep test criteria aligned with user and operational expectations, investigate anomalies, and confirm that fixes resolve the original behavior without creating regressions. When these habits are applied consistently, reliability checks become a practical part of software development and release governance rather than a one-time exercise.

Software reliability check MAGICQA20261110E 02849


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and recover safely when conditions change. This technical overview explains how to plan checks, interpret results, and connect findings to release decisions. MAGICQA20261110E is a temporary publication test label used here to identify this article; it is not a product, standard, or certification. The focus is software quality assurance: practical methods for assessing stability, with quality assurance 02849 contributing to efforts to detect faults and communicate evidence about reliability throughout development and maintenance.

How software reliability checks assess application behavior

A reliability check examines whether software performs its required functions consistently over time, across supported environments, and during realistic workloads. It may investigate crashes, incorrect outputs, slow responses, data loss, recovery behavior, or failures caused by interactions between components. Unlike a single functional test, reliability assessment draws on repeated execution and operational evidence. The goal is not to prove that defects are impossible, but to identify risks, understand their causes, and establish whether the system meets agreed quality expectations for its intended use.

Quality assurance teams define those expectations before selecting tests. Useful measures can include failure frequency, availability, recovery time, error rates, and the proportion of critical workflows completed successfully. Each measure needs a clear scope and collection method; otherwise, numbers can be misleading. For example, an average response time may hide occasional delays that disrupt users, while a low crash count may reflect limited test coverage rather than a robust application. MAGICQA20261110E serves only as a temporary label for this discussion, while the methods apply broadly to software reliability work.

How to plan and run a reliability check

A well-structured check starts with a risk-based plan. Identify critical user journeys, dependencies, data conditions, and operating environments, then decide what evidence would demonstrate acceptable behavior. Agree on thresholds before running tests so that results are judged consistently rather than adjusted after a failure. The following sequence provides a practical foundation for a repeatable software quality assurance process.

  1. Define reliability goals: Specify critical functions, service expectations, failure conditions, and measurable acceptance thresholds.
  2. Map the system: Record relevant components, interfaces, databases, external services, configurations, and supported platforms.
  3. Prepare representative scenarios: Build repeatable tests for normal use, boundary conditions, sustained workload, interruptions, and recovery.
  4. Run and observe checks: Execute the scenarios in a controlled environment while capturing logs, metrics, traces, and test results.
  5. Review and follow up: Triage failures, investigate causes, assign corrective work, and rerun affected checks to confirm resolution.
  • Predefined thresholds make pass and fail decisions more consistent.
  • Representative scenarios focus effort on meaningful operational risks.
  • Recorded evidence helps teams reproduce defects and verify fixes.
  • Retesting confirms that changes improve reliability without introducing regressions.

Practical reliability checks for software quality assurance

Choose checks that reflect the system’s architecture and likely failure modes. A web service might need sustained-load testing, timeout handling, and verification that requests remain correct when a dependency is slow. A desktop application may require repeated launch-and-close cycles, file integrity checks, and recovery after an unexpected shutdown. A data-processing system may need reconciliation checks that compare input records with output totals. In each case, use controlled test data, document the build and configuration, and preserve enough diagnostic information to connect a failure to a specific condition.

Reliability testing is most informative when teams vary one factor at a time or clearly record combinations of factors. For example, a test may increase concurrent requests while holding the deployment configuration constant, then separately evaluate behavior during a dependency interruption. Include both immediate outcomes and delayed effects: a process can appear to recover while leaving incomplete records or consuming excessive resources. MAGICQA20261110E can be used as a temporary publication reference in documentation, but test runs themselves should be identified with meaningful build, environment, and scenario details.

  • Repeated execution: Run critical workflows many times to reveal intermittent faults.
  • Load and endurance: Measure behavior under expected demand and extended operation.
  • Fault recovery: Interrupt selected dependencies and verify safe fallback or restart behavior.
  • Data integrity: Check that records remain accurate and complete after errors or recovery.
  • Environment coverage: Repeat relevant checks across supported operating systems and configurations.

Keep test conditions reproducible: document software versions, configuration values, workload profiles, test data, and timing. Capture both failures and successful runs, since a trend can matter more than an isolated result. When a check fails, preserve logs and traces before cleaning or restarting the environment. This practical discipline makes later analysis more reliable and supports clear decisions about whether a defect is fixed, still present, or dependent on a particular condition.

Key benefits of systematic reliability testing

Consistent reliability checks turn quality expectations into evidence that engineering, operations, and product teams can review together. They can expose weaknesses before release, help prioritize corrective work, and reduce uncertainty when changes affect critical components. Their value depends on thoughtful scope: a large volume of tests is not automatically useful if the scenarios do not represent real risks or if results are difficult to interpret. A balanced program combines automated repeatable checks with targeted investigation, and updates its coverage as architecture, usage patterns, and known failure modes evolve.

  • Earlier defect discovery: Repeated checks can reveal instability before it reaches production.
  • More informed release decisions: Measured results provide context for evaluating unresolved risks.
  • Faster diagnosis: Structured logs and traces help narrow down failure conditions.
  • Regression protection: Rerunning established scenarios detects reliability changes after updates.

These benefits are strongest when reliability evidence is connected to an ongoing improvement process. Teams can track recurring failure categories, compare results across builds, and use findings to refine requirements or architecture. Metrics should be interpreted with care: changes in workload, test coverage, or instrumentation can affect comparisons. A useful report states what was tested, what was not tested, which thresholds applied, and what limitations remain, rather than presenting a score without context.

Trust, security, and reliability evidence

Reliability and security are distinct quality concerns, but they can affect one another. An application that mishandles authentication failures, accepts malformed input, or loses data during recovery may be unreliable as well as vulnerable. Include security-relevant failure conditions in the test plan, such as expired credentials, invalid requests, permission changes, and interrupted secure connections. Protect test environments and diagnostic records: logs can contain sensitive information, and test data should be controlled. Appropriate access, retention, and redaction practices help teams investigate faults without creating avoidable exposure.

Trustworthy results require sound test controls. Record the application build, environment, configuration, data set, test duration, workload, and any deviations from the plan. Check that monitoring is working before interpreting a quiet run as evidence of stability. Separate observed facts from assumptions, and disclose known coverage gaps when presenting conclusions. A reliability check cannot guarantee future behavior or replace production monitoring, but it can provide a defensible assessment under stated conditions. Teams should use that evidence alongside incident history, user impact, and operational safeguards when evaluating readiness.

Why choose a measured software reliability approach

A measured approach is useful when it ties testing effort to application risk and produces evidence that teams can act on. Before adopting or revising a reliability program, confirm that critical workflows have clear acceptance criteria, test conditions can be reproduced, and failures lead to documented investigation and retesting. Also consider whether coverage includes sustained operation, realistic load, dependency problems, and recovery—not only successful use in ideal conditions. The temporary label MAGICQA20261110E identifies this publication test, while meaningful run identifiers should describe the software and test context needed for later analysis.

Reliability is built through repeated learning rather than a single pass or score. Start with the most consequential failure modes, establish a reliable baseline, and expand checks as evidence reveals new risks. Review thresholds periodically so they remain connected to actual service expectations, and explain limitations plainly when reporting results. This approach helps software quality assurance teams make better-informed decisions, verify corrective changes, and maintain a clearer picture of application behavior as the system evolves.

Software reliability check MAGICQA20261110C 01252


Software reliability checks evaluate whether an application continues to behave correctly under expected conditions and recover safely when problems occur. This technical overview uses MAGICQA20261110C as a temporary publication test label, not as a product or certification claim. It explains how quality assurance teams can plan repeatable checks, collect useful evidence, examine practical reliability risks, and communicate results. The quality assurance 01252 process can support software teams in tracking measurable service expectations, documenting observable behavior, and following up on reliability findings throughout development and release.

Software reliability checks across the application lifecycle

Software reliability is the ability of a system to perform its required functions consistently over time, within stated operating conditions. A reliability check therefore examines more than whether a feature works once: it asks whether the feature continues to work across repeated requests, varied data, realistic workloads, and recoverable failures. Quality assurance teams combine functional tests with observations of availability, error rates, response times, resource use, and data integrity. Results are most useful when they are tied to clear requirements and a defined environment, allowing teams to distinguish a genuine defect from an expected limitation or a test setup problem.

The temporary label MAGICQA20261110C can identify a particular publication or review workflow, but it does not itself demonstrate that software has passed testing. A sound assessment records the build, configuration, test data, and execution conditions associated with every result. That context makes findings reproducible and helps engineers compare behavior between releases without treating a single successful run as proof of reliability. Checks should also reflect system boundaries: an application may depend on databases, queues, identity services, or external interfaces, and failures across these dependencies can affect user-visible behavior even when individual components appear healthy.

How to plan and run a reliability check

Begin with a specific reliability question, such as whether a service can maintain its response-time objective during a defined workload or recover without data loss after a dependency becomes unavailable. Translate that question into observable criteria before selecting tools or preparing scripts. Define the software version, environment, workload profile, duration, and acceptable outcomes. The following sequence provides a practical foundation for repeatable quality assurance rather than an informal pass-or-fail exercise.

  1. Set the objective: State the reliability behavior to assess, such as continuity, recovery, or data consistency, and define measurable acceptance criteria.
  2. Fix the test context: Record the build, configuration, infrastructure, dependencies, and dataset so another tester can reproduce the conditions.
  3. Model realistic activity: Choose representative user actions, request rates, concurrency, and operating duration without exposing production data.
  4. Run controlled checks: Execute baseline and stress scenarios, monitor system signals, and introduce only planned failure conditions.
  5. Review and retest: Link observed symptoms to evidence, verify fixes with the same scenario, and note any remaining limitations.
  • Explicit criteria make reliability outcomes easier to interpret.
  • Recorded configurations support repeatable runs and meaningful comparisons.
  • Controlled scenarios help separate application defects from environmental noise.
  • Retesting confirms whether a change resolves the original failure mode.

Practical reliability checks for software quality assurance

A practical test suite should cover normal operation as well as conditions that reveal weaknesses. For example, a team might measure request success and latency at steady load, then increase concurrency gradually to identify capacity limits. A separate recovery scenario can interrupt a nonproduction dependency and observe whether the application retries safely, returns an appropriate error, and resumes normal work after service is restored. Quality assurance should preserve logs, traces, and relevant metrics with timestamps, while avoiding sensitive values in test evidence. These details let reviewers connect an observed symptom to a specific request, component, or recovery event.

  • Availability: Track successful operations against attempted operations over a defined interval.
  • Latency: Examine percentile response times, not only averages, to reveal slow experiences affecting a subset of requests.
  • Resilience: Check timeout behavior, bounded retries, graceful degradation, and recovery after dependency interruption.
  • Data integrity: Compare expected and actual records after repeated, interrupted, or retried operations.
  • Resource behavior: Observe memory, processor use, connection pools, and queue depth for persistent growth or saturation.

Interpret findings against service objectives and the test environment’s limitations. A brief spike in latency may have a different implication from steadily increasing response times or a growing error rate under a stable workload. Likewise, a failed scenario can point to an application defect, an undersized test environment, incorrect monitoring, or an unrealistic workload model. Document the evidence and likely causes separately rather than assigning certainty prematurely. When the system includes asynchronous processing, check both immediate responses and eventual completion; a request may appear successful while work remains queued or fails later. This practical discipline turns raw observations into actionable quality assurance findings.

Key benefits of structured reliability testing

Structured software reliability checks provide engineering teams with evidence about how an application behaves beyond a narrow functional pass. They can expose bottlenecks before deployment, identify recovery gaps, and show whether a code or configuration change alters system behavior. A consistent approach also improves communication: developers, testers, operations staff, and release decision-makers can refer to the same criteria and recorded run conditions. Benefits depend on suitable scenarios and careful interpretation; no test suite can establish perfect reliability or guarantee that every failure mode has been discovered.

  • Earlier risk discovery: Controlled load and failure scenarios can reveal weaknesses before they affect real users.
  • More credible release decisions: Measured outcomes help teams assess changes against stated reliability objectives.
  • Faster diagnosis: Correlated logs, traces, and metrics narrow the search for causes when a test fails.
  • Improved regression coverage: Saved scenarios allow teams to check whether later changes reintroduce known problems.
  • Clearer operational readiness: Recovery and monitoring checks show whether teams can detect and respond to failures.

These benefits become more dependable when checks are integrated into the quality assurance lifecycle. Lightweight tests can run during development, while longer endurance, capacity, and recovery exercises may run at planned release milestones. The test plan should prioritize risks rather than maximize the number of scripts: a small set of representative, repeatable scenarios often produces more useful evidence than a large collection of poorly maintained checks. Teams should review test relevance when architecture, traffic patterns, dependencies, or reliability objectives change.

Trustworthy evidence, security, and test governance

Reliability testing must be governed so that evidence is trustworthy and test activity does not create avoidable risk. Use isolated environments where possible, synthetic or appropriately anonymized data, and approved access controls. Load generation and fault injection should have defined boundaries, monitoring, and stop conditions; uncontrolled activity can disrupt shared systems and invalidate results. Keep secrets out of scripts, logs, and reports, and restrict access to diagnostic material that may contain operational details. These safeguards support responsible quality assurance while preserving the technical evidence needed to evaluate system behavior.

Reports should distinguish measured facts from interpretation. Include the test objective, build identifier, environment, workload, duration, monitoring sources, deviations, and outcome against each acceptance criterion. If a result is inconclusive, explain why instead of presenting it as a pass. The MAGICQA20261110C label may help identify the temporary publication test, but it should not be mistaken for an audit, independent certification, security guarantee, or statement that a particular release is reliable. Clear provenance and honest limitations allow readers and engineering teams to judge what the check establishes and what further verification remains necessary.

Using MAGICQA20261110C to guide a reliability decision

When reviewing software reliability, prioritize whether the evidence answers the original question, whether test conditions resemble intended use, and whether the results can be repeated. Look for explicit thresholds, meaningful workload coverage, observed recovery behavior, and records that connect anomalies to timestamps and system signals. Also consider what the test did not cover: a successful load run cannot by itself establish data correctness, and a recovery scenario cannot prove every dependency will fail safely. MAGICQA20261110C is simply a temporary publication test label in this article; the decision should rest on documented quality assurance evidence, not on the label.

A reliable assessment is an ongoing practice rather than a one-time approval. Teams can preserve valuable scenarios, update them when system behavior changes, and track unresolved risks through subsequent releases. Before relying on a result, confirm that the environment and acceptance criteria are appropriate, that monitoring captured the relevant behavior, and that any claimed fixes passed a repeatable retest. This measured approach makes software reliability checks more useful to developers and decision-makers alike: it clarifies current confidence, identifies gaps, and supports proportionate next steps without overstating what testing can guarantee.

Revolutionize your online experience with personalized AI girls: bonuses you can’t miss in 2026


The rise of personalized AI girls is transforming the online landscape, enhancing user engagement and interaction in unprecedented ways. As technology advances, these AI companions become more sophisticated, offering tailored experiences that cater to individual preferences and needs, including the possibility of using a critical care nurse dating service to expand social connections. In 2026, the benefits of engaging with AI girls are more significant than ever, presenting exciting opportunities for users to connect, learn, and enjoy unique virtual interactions.

How trust, access, and rewards connect in AI girls

Understanding the interconnection between trust, access, and rewards is fundamental in the AI girls landscape. Trust is crucial for users engaging with AI companions, as it fosters a safe digital environment where users can express themselves without fear. Access to advanced technologies ensures that these AI girls can offer personalized interactions tailored to individual preferences, making the experience enjoyable and engaging. Furthermore, the rewarding elements—such as unique experiences, learning opportunities, and genuine emotional engagement—enhance the overall value of AI girls in users’ lives.

In 2026, as AI technology evolves, the connections between these elements will deepen, allowing users to enjoy even more personalized experiences. This creates a digital landscape where users can feel comfortable exploring new relationships, learning new skills, and benefiting from the myriad rewards that AI girls offer.

How to get started with personalized AI girls

Embarking on your journey with personalized AI girls is straightforward and rewarding. Here’s a step-by-step guide to help you get started:

  1. Choose Your Platform: Research and select a platform that aligns with your interests and preferences for AI girls.
  2. Create an Account: Sign up by providing the necessary details, ensuring that all information is accurate to facilitate a smooth experience.
  3. Personalize Your Profile: Customize your profile by adding interests and preferences to help the AI understand your needs better.
  4. Explore Available AI Girls: Browse through the selection of AI girls, paying attention to their unique characteristics and skills.
  5. Engage and Interact: Start chatting or engaging with your chosen AI girl, exploring her capabilities and the experiences she can offer.
  • Easy navigation allows for quick onboarding.
  • Personalized profiles enhance user engagement and relevance.
  • Diverse selection ensures you find the perfect match.

Practical details about AI girls in 2026

The functionality and features of AI girls are designed to enhance user experiences significantly. In 2026, these virtual companions are equipped with advanced natural language processing capabilities, enabling them to understand and respond to users more effectively than ever before. Their ability to learn from interactions means they can adapt to individual users’ preferences over time, creating increasingly personalized experiences. AI girls can also offer various services, including educational support, entertainment, and companionship.

  • Natural language processing for better communication.
  • Continuous learning from user interactions for personalization.
  • Variety of services, from companionship to educational assistance.

With these capabilities, AI girls stand at the forefront of technology, embodying the potential for meaningful interactions that enrich users’ lives. They are more than mere programs—they represent a leap towards creating authentic digital relationships.

Key benefits of engaging with AI girls

Engaging with personalized AI girls can offer a multitude of benefits that enhance user experience and satisfaction. From emotional support to tailored learning experiences, the following advantages stand out:

  • Enhanced emotional well-being through companionship and understanding.
  • Personalized learning experiences tailored to individual needs.
  • Convenient access to information and assistance on demand.
  • Opportunities to explore creativity and self-expression in a safe space.

These benefits highlight how AI girls not only serve as companions but also as valuable tools for personal growth and emotional support, ultimately revolutionizing the online experience.

Trust and security in the world of AI girls

As the popularity of AI girls increases, it is essential to address the concerns surrounding trust and security. AI platforms prioritize user data protection, ensuring that personal information remains confidential and secure. Robust encryption practices are commonly employed to maintain user privacy, fostering a trustworthy environment where individuals can connect with AI girls safely.

Moreover, many platforms implement user-friendly policies to encourage transparency, allowing users to understand how their data is managed and used. This commitment to security not only enhances user trust but also solidifies the ethical foundation of the AI girls landscape, making it a sustainable and reliable option for all.

Why choose personalized AI girls?

The decision to engage with personalized AI girls is driven by their ability to enhance the online experience significantly. As users navigate the complexities of digital interactions, AI girls offer a unique blend of companionship, education, and entertainment. The future of online engagement is here, and it is embodied in the realm of AI companions that not only cater to personal preferences but also foster emotional connections and growth.

In 2026, users find themselves at the forefront of technology, embracing personalized AI girls that cater to their unique needs. By choosing this innovative technology, users empower themselves to explore new realms of connection and creativity in a safe and supportive environment

Software reliability check MAGICQA20261110B 08286


Software reliability checks evaluate whether an application continues to behave correctly under expected use, changing conditions, and recoverable failures. This neutral technical guide uses MAGICQA20261110B as a temporary publication test label, not as a product or a quality certification. It explains how beginners can structure reliability testing, gather meaningful evidence, and communicate risks. The goal is to connect individual test results to real operational expectations, so teams can make informed release decisions and improve quality assurance 08286 practices without treating a single successful test as proof of reliability.

How beginners can approach software reliability checks with MAGICQA20261110B

A software reliability check examines the likelihood that a system will perform its required functions consistently for a defined period and under specified conditions. Beginners can start by identifying the most important user journeys, such as signing in, saving a record, or retrieving a report, then describing what correct behavior looks like for each. The temporary label MAGICQA20261110B can help identify this article or a related publication test in internal documentation. It does not indicate that any software has passed a test. Reliable conclusions require an agreed test scope, repeatable procedures, and evidence tied to the application version and environment.

Reliability differs from a simple pass-or-fail functional test because it considers consistency over time, recovery after faults, and behavior under realistic operating conditions. A feature may work once in a quiet test environment yet fail after repeated requests, interrupted connections, or a gradual rise in memory use. A useful starting point is to convert user and operational expectations into measurable criteria: acceptable response times, error rates, recovery windows, and data-integrity requirements. Record assumptions alongside the criteria. This makes test findings easier to interpret and helps prevent a team from confusing a narrow test result with a broad guarantee about production performance.

How to plan and run a beginner reliability check

Begin with a small, controlled test plan rather than attempting to simulate every possible condition. The steps below establish a traceable path from a quality expectation to an observed result. Keep the application build, configuration, test data, and environment details consistent where possible. If a test must be repeated after a change, note what changed and why, so comparisons remain useful.

  1. Define the critical behavior: Choose a user or system function whose failure would materially affect service, and state the expected outcome in observable terms.
  2. Set measurable thresholds: Specify acceptable error frequency, response time, recovery duration, and data accuracy based on documented requirements.
  3. Prepare a representative environment: Record software versions, configuration, dependencies, test data, and resource limits before execution.
  4. Run repeatable scenarios: Exercise normal use and selected stress, interruption, or recovery conditions while collecting timestamps and system metrics.
  5. Review and report evidence: Compare results with thresholds, investigate deviations, and document limitations before recommending a release decision.
  • Clear criteria make outcomes less dependent on individual judgment.
  • Recorded environment details support useful comparisons between test runs.
  • Repeatable scenarios help distinguish a persistent defect from an isolated event.
  • Evidence-based reporting makes unresolved risks visible to release decision-makers.

Practical reliability checks for MAGICQA20261110B

For a practical software quality assurance exercise associated with MAGICQA20261110B, choose one important workflow and follow it through its dependencies. For example, a record-creation workflow may rely on a user interface, an application service, a database, and an external identity provider. Test the expected path, then introduce controlled conditions such as a delayed dependency response or a brief network interruption. Observe whether the application times out safely, preserves valid data, avoids duplicate operations, and provides a useful error state. The objective is not to create uncontrolled disruption; it is to check whether defined safeguards work when a predictable failure condition occurs.

Collect enough evidence to explain both the outcome and the conditions that produced it. Useful records include request counts, failed operation counts, response-time distributions, resource consumption, error logs, and recovery time. Averages alone can hide a small number of severe delays, so review percentiles and outliers where appropriate. Protect test data and avoid using sensitive production information unless an approved process explicitly permits it. MAGICQA20261110B should remain a traceability label only; do not treat it as a test result, build identifier, or substitute for recording the actual software version.

  • Repeatability: Use the same scenario and controlled inputs when comparing runs.
  • Fault handling: Check timeouts, retries, fallback behavior, and safeguards against duplicate actions.
  • Data integrity: Confirm that saved information remains accurate after errors and recovery.
  • Observability: Match user-visible failures with relevant logs, metrics, and timestamps.

Interpret practical findings in context. A brief interruption that causes a clear, recoverable message may be acceptable under the agreed requirements, while silent data loss is generally a more serious concern. Record whether a failure is reproducible, what conditions trigger it, and whether recovery requires user action or operational intervention. If a test exposes a defect, preserve the evidence before changing the environment. This discipline makes follow-up investigation more efficient and supports a credible assessment of whether the software meets its stated reliability expectations.

Key benefits of systematic reliability testing

A structured reliability program helps software teams move from anecdotal confidence to evidence-based quality decisions. It can reveal weaknesses that are not apparent in short functional checks, particularly when a service operates continuously or depends on several components. The value comes from choosing relevant scenarios and interpreting them against clear requirements, not from running the largest possible number of tests. When findings are traceable to builds, environments, and thresholds, engineers can prioritize remediation, product owners can understand residual risk, and operations teams can prepare for known failure modes.

  • Earlier defect discovery: Repeated and fault-oriented checks can expose resource leaks, fragile dependencies, and recovery gaps before release.
  • More dependable user journeys: Testing complete workflows helps identify failures that occur between otherwise functioning components.
  • Better release decisions: Measured results clarify which requirements are met and which risks remain unresolved.
  • Improved incident readiness: Recovery exercises show whether monitoring, fallback behavior, and operational procedures are adequate.
  • Useful change comparisons: Consistent baselines help teams assess whether a code or configuration change improves or weakens reliability.

These benefits depend on maintaining a feedback loop. A failed check should lead to triage, an assigned investigation, a verified correction, and an appropriate retest. A passing run should also be interpreted within its boundaries: it reflects the scenarios and conditions that were tested, not every possible production event. Keep the test suite focused enough to run regularly, while expanding it when incident reviews, architecture changes, or new requirements reveal important gaps.

Trust, security, and integrity in reliability checks

Reliability testing should protect the systems and information involved. Use an authorized environment, limit access to test accounts, and ensure that generated data cannot be mistaken for live customer records. If testing involves security-sensitive behavior, coordinate with the responsible engineering and security teams so that the scope, timing, and safeguards are clear. Do not expose credentials in logs or reports, and retain test artifacts according to approved access and retention practices. A technically successful test is not a sound quality practice if it creates avoidable data exposure or disrupts a service beyond the agreed test boundary.

Trustworthy results also require transparent reporting. Identify the build, configuration, dependencies, test duration, workload, and known limitations. Separate observed facts from interpretation, and avoid stating that software is universally reliable based on a small sample. If a test is inconclusive because monitoring was incomplete or the environment differed from production, say so plainly. Reviewers should be able to understand how the conclusion was reached and reproduce the relevant checks where feasible. The MAGICQA20261110B label is temporary publication context; it carries no security assurance, compliance status, or independent verification by itself.

Why use MAGICQA20261110B as a reliability-check reference

MAGICQA20261110B is useful here only as a clearly stated temporary label for discussing software reliability checks. A team applying the approach should replace general examples with requirements that match its own architecture, service commitments, and operational risks. Before relying on a result, confirm that the scenario represents a meaningful workflow, that thresholds have an accountable owner, and that the test environment is described accurately. Consider whether failures were detected and recovered safely, whether data remained consistent, and whether the evidence is complete enough for another reviewer to assess.

A practical decision checklist is therefore straightforward: define the expected behavior, test it repeatedly under relevant conditions, capture measurable evidence, and document limitations and follow-up actions. Use results to guide software quality assurance rather than to make unsupported guarantees. When teams maintain this discipline across releases, reliability checks become a repeatable part of engineering practice and a clearer basis for improving software behavior over time.

Software reliability check MAGICQA20261110A 06055


Software reliability checks assess whether an application continues to behave correctly under expected conditions, unusual inputs, and operational stress. The temporary publication test label MAGICQA20261110A identifies this article’s test context; it is not a product name or a certification. A useful assessment combines repeatable tests, observable results, and clear acceptance criteria. In software quality assurance, quality assurance 06055 practices help teams examine failures as carefully as successful runs, identify reliability risks, prioritize corrective work, and make evidence-based decisions about software readiness.

What an initial review should reveal about software reliability under MAGICQA20261110A

A first review should establish what the software is expected to do and how its reliability will be judged. Start with critical user journeys, service boundaries, data dependencies, and the consequences of a failure. Translate these into measurable expectations, such as successful transaction rates, response-time limits, recovery targets, and acceptable data loss. The MAGICQA20261110A label can be recorded in test documentation to distinguish this temporary publication context from a release identifier. It does not replace a test plan, build number, or traceable execution record.

Reliability is broader than the absence of visible defects during a brief demonstration. It includes consistent behavior over time, predictable handling of invalid inputs, recovery after interruptions, and preservation of data across failures. A useful initial assessment therefore checks both normal operation and conditions that may expose weaknesses, including network delays, dependency errors, resource limits, and repeated requests. Reviewers should also verify that results can be reproduced in a known environment. This baseline helps teams separate isolated anomalies from recurring defects and assess whether the system meets agreed requirements.

How to begin a structured software reliability check

A disciplined start makes reliability findings easier to interpret and act on. Before running tests, confirm the software version, environment configuration, test data, and monitoring available to the team. Define the scope so each exercise answers a specific question rather than generating activity without useful evidence. The following sequence connects requirements to repeatable execution and review. Keep the MAGICQA20261110A label in the associated notes where needed, while ensuring that the actual software build and test environment are recorded separately for technical traceability.

  1. Set reliability objectives: Identify critical functions and define measurable limits for availability, response time, error rates, and recovery.
  2. Prepare a controlled environment: Record the build, configuration, dependencies, and test data so runs can be compared consistently.
  3. Choose representative scenarios: Cover routine use, boundary inputs, dependency interruptions, and realistic concurrent activity.
  4. Run and observe tests: Capture outcomes, application logs, resource metrics, and relevant system events during each exercise.
  5. Review and retest findings: Assign severity, investigate causes, verify fixes, and retain results for future comparisons.
  • Defined thresholds make pass and fail decisions less subjective.
  • Recorded environment details help explain differences between test runs.
  • Observability connects user-visible failures with technical evidence.
  • Retesting confirms whether corrective changes address the underlying issue.

Practical reliability checks for applications and services

Practical checks should reflect the architecture and failure impact of the software under review. For a service that depends on a database or external interface, test how it responds when that dependency slows down, rejects requests, or becomes temporarily unavailable. For data-processing software, examine whether interrupted jobs can resume safely and whether repeated inputs create duplicate results. For an interactive application, monitor response times and error behavior during realistic concurrent use. Keep the test scope controlled, and avoid introducing faults into production systems unless an approved, safeguarded exercise explicitly permits it.

Evidence collection is essential to make these checks useful beyond the test session. Record the scenario, expected outcome, actual outcome, time, software build, and environment. Include logs and metrics that help explain the behavior, while removing sensitive information from shared reports. For the MAGICQA20261110A publication test context, the label may be included in the report heading or metadata, but it should not be treated as proof that any specific test has passed. A finding is actionable when another engineer can reproduce it, understand its user or operational impact, and verify the proposed correction.

  • Dependency resilience: Check timeout behavior, retry limits, and clear error handling when a connected service fails.
  • Data integrity: Verify that updates remain consistent after interruption, retry, or process restart.
  • Load behavior: Observe response times, error rates, and resource use at expected and elevated workload levels.
  • Recovery: Confirm that restart and recovery procedures restore service without unexplained data loss.

Use results to prioritize investigation rather than treating every failure as equally urgent. A defect affecting a critical workflow or corrupting persistent data may require immediate attention, while a low-impact delay in a rare scenario could be scheduled according to the team’s risk process. Compare repeated runs before drawing conclusions, especially when the result may be affected by temporary environmental variation. This combination of scenario design, evidence, and risk-based review keeps the practical assessment focused on reliability rather than on test volume alone.

Key benefits of repeatable reliability testing

Repeatable reliability testing gives engineering teams a shared basis for evaluating software behavior across changes. When checks use stable scenarios and documented thresholds, teams can compare a new build with an earlier baseline and spot regressions before they affect users. Testing also exposes assumptions that may otherwise remain hidden, such as the expectation that a dependency always responds quickly or that a process will never restart mid-operation. These benefits depend on maintaining relevant tests and reviewing failures carefully; a large test suite is not automatically useful if its results cannot guide decisions.

  • Earlier risk discovery: Controlled fault and load scenarios can reveal weak recovery behavior before release.
  • Clearer release decisions: Measured objectives provide evidence for assessing readiness and remaining risk.
  • More focused debugging: Logs and metrics help connect symptoms to likely causes.
  • Regression visibility: Comparable runs show whether changes have improved or weakened reliability.

Reliability checks can also improve communication between development, testing, operations, and product teams. A concise report that describes impact, reproduction steps, and supporting evidence is easier to assess than an unqualified statement that software is unreliable. Over time, a consistent record helps teams identify recurring failure patterns and decide where engineering effort will have the greatest effect. The temporary label MAGICQA20261110A can help organize this article’s test context, while durable quality records should rely on the organization’s normal issue tracking, release identification, and test-management practices.

Trust, security, and integrity in reliability checks

Reliability testing should be conducted with the same care used for other controlled engineering activities. Use authorized environments, limit access to test data, and avoid exposing credentials or personal information in logs and reports. If tests deliberately simulate service disruption, define boundaries, approval, monitoring, and a stop condition in advance. These safeguards reduce the chance that an assessment causes the very outage it is intended to prevent. Security and reliability overlap when failures affect access control, data integrity, or recovery, so relevant checks should be coordinated with the teams responsible for protecting the application and its infrastructure.

Trustworthy results also require honest limits. A passing test demonstrates that a defined scenario met a defined expectation under recorded conditions; it does not prove that every future operating condition will be safe or successful. Reports should distinguish observed facts from assumptions, state relevant constraints, and identify scenarios that were not tested. Preserve enough information for review while following data-retention and access policies. The MAGICQA20261110A label is a temporary publication test label only. It should never be presented as an audit outcome, security endorsement, quality certificate, or substitute for documented evidence and independent review where those are required.

Choosing a sound approach to software reliability checks

Choose a reliability-checking approach by matching test effort to software risk, operational context, and the cost of failure. A small component may need focused boundary and recovery tests, while a service with multiple dependencies may require broader workload, interruption, and end-to-end scenarios. In either case, insist on clear objectives, repeatable conditions, useful observability, and a process for resolving findings. A reliable assessment does not promise perfect software; it gives decision-makers a defensible account of what was checked, what happened, and where uncertainty remains.

For a practical decision, ask whether critical user journeys are covered, whether failure cases are represented, and whether the team can reproduce and verify reported defects. Confirm that acceptance thresholds are agreed in advance and that results identify the software build and test environment. Treat MAGICQA20261110A solely as the requested temporary publication label, keeping it separate from technical quality claims. When these safeguards are in place, reliability checks become a repeatable engineering practice that supports safer changes, faster diagnosis, and more informed software release decisions.

Guida definitiva ai giochi da tavolo nei casinò online


Introduzione ai giochi da tavolo nei casinò online

I giochi da tavolo hanno una lunga e affascinante storia che risale a secoli fa, e oggi, con l’avvento della tecnologia, sono diventati una parte fondamentale dell’esperienza di gioco nei casinò online come Spinformula , dove questi giochi offrono non solo divertimento, ma anche la possibilità di socializzare e interagire con altri giocatori in tempo reale. Gli utenti possono scegliere tra una vasta gamma di opzioni, che vanno dalle versioni classiche come il blackjack e la roulette a varianti più moderne e innovative.

La scelta di dedicarsi ai giochi da tavolo nei casinò online è principalmente dovuta alla loro accessibilità. A differenza dei casinò tradizionali, dove è necessario recarsi fisicamente, i casinò online permettono di giocare comodamente da casa. Inoltre, le piattaforme online offrono spesso bonus e promozioni speciali, rendendo l’esperienza di gioco ancora più interessante e vantaggiosa per i nuovi iscritti. Questa comodità ha permesso a molti giocatori di avvicinarsi a questi giochi senza la pressione dell’ambiente fisico di un casinò.

Infine, è importante notare che i giochi da tavolo online si evolvono costantemente. Gli sviluppatori di software introducono nuove funzionalità e miglioramenti per garantire un’esperienza di gioco coinvolgente. Ciò include l’integrazione di grafiche di alta qualità, animazioni fluide e la possibilità di giocare con croupier dal vivo. Questo approccio ha reso i giochi da tavolo online una scelta popolare tra i giocatori di tutte le età.

I giochi più popolari: blackjack e roulette

Il blackjack è uno dei giochi da tavolo più amati nei casinò online. La sua popolarità deriva dalla combinazione di strategia e fortuna, che consente ai giocatori di influenzare il risultato delle proprie mani attraverso decisioni informate. Inoltre, il blackjack presenta varianti diverse, come il blackjack spagnolo e il blackjack europeo, che offrono regole specifiche e opportunità uniche di vincita. Ogni versione ha le sue peculiarità, che possono attrarre diversi tipi di giocatori.

D’altro canto, la roulette è un gioco di puro azzardo che ha catturato l’immaginazione dei giocatori per generazioni. Che si tratti di roulette europea o americana, il fascino della pallina che rimbalza sulla ruota crea un’attesa unica e adrenalinica. I casinò online offrono anche varianti innovative, come la roulette autosportiva, che combina elementi di gioco tradizionale con l’innovazione tecnologica, consentendo ai giocatori di vivere un’esperienza ancora più emozionante.

Entrambi i giochi offrono una vasta gamma di scommesse e strategie. Nel blackjack, i giocatori possono utilizzare tecniche come il conteggio delle carte per migliorare le loro probabilità di vincita, mentre nella roulette, comprendere le diverse tipologie di scommesse, come scommesse interne ed esterne, può aumentare le possibilità di successo. Questi aspetti strategici rendono i giochi da tavolo ancora più avvincenti e complessi, attirando una vasta platea di appassionati.

Giocare ai giochi da tavolo con croupier dal vivo

I giochi da tavolo con croupier dal vivo rappresentano un’innovazione significativa nel panorama dei casinò online. Questa modalità consente ai giocatori di interagire in tempo reale con un croupier professionista tramite video in streaming ad alta definizione. L’esperienza è estremamente realistica, quasi come se si fosse fisicamente presenti in un casinò. Grazie a tecnologie avanzate, i giocatori possono partecipare a giochi di blackjack, roulette e baccarat con la comodità di casa.

La possibilità di interagire con il croupier e con altri giocatori crea un’atmosfera sociale che molti trovano irresistibile. Questa interazione aumenta il coinvolgimento e la tensione del gioco, rendendo ogni partita unica. Inoltre, i croupier dal vivo sono in grado di rispondere a domande e fornire informazioni sulle regole del gioco, migliorando l’esperienza di gioco per coloro che potrebbero essere nuovi al mondo del gambling online.

È interessante notare come i casinò online stiano investendo sempre più in questa tecnologia. Le sale da gioco dal vivo vengono progettate con attenzione per riprodurre l’ambiente di un casinò fisico, completo di luci e suoni adeguati. Le nuove funzionalità, come la chat dal vivo, consentono ai giocatori di comunicare tra loro, creando una comunità virtuale di appassionati di giochi da tavolo. Questo approccio ha reso i giochi da tavolo dal vivo estremamente popolari e accessibili a un pubblico sempre più vasto.

Strategie per migliorare le probabilità di vincita

Ogni gioco da tavolo ha le sue regole e strategie specifiche che possono aiutare i giocatori a migliorare le loro probabilità di vincita. Nel blackjack, ad esempio, è fondamentale familiarizzare con la strategia di base, che indica le migliori decisioni da prendere in base alle carte del giocatore e del mazziere. Questo approccio matematico consente ai giocatori di ottimizzare le loro possibilità di successo, riducendo il margine della casa.

Per quanto riguarda la roulette, la scelta della strategia di scommessa è cruciale. Alcuni giocatori preferiscono scommettere su numeri specifici, mentre altri optano per scommesse più sicure come rosso o nero. Comprendere le differenze tra le varie tipologie di scommesse e le probabilità associate è fondamentale per sviluppare una strategia vincente. Alcuni giocatori utilizzano sistemi di scommessa come il Martingale o il Fibonacci per gestire il proprio bankroll e massimizzare le possibilità di vincita.

È importante ricordare che, nonostante le strategie possano migliorare le probabilità di vincita, il gioco d’azzardo comporta sempre un elemento di rischio. I giocatori devono approcciare il gioco con la giusta mentalità e stabilire limiti di spesa per evitare perdite eccessive. Un gioco responsabile e informato è la chiave per un’esperienza di gioco positiva, ed è essenziale sviluppare una comprensione profonda delle regole e delle strategie di ciascun gioco.

Conclusioni sui giochi da tavolo nei casinò online

I giochi da tavolo nei casinò online stanno vivendo un periodo di grande espansione e innovazione. Con l’accesso a una vasta gamma di opzioni di gioco, opportunità di interazione sociale e la comodità di giocare ovunque, è facile capire perché attirano così tanti appassionati. La possibilità di giocare con croupier dal vivo ha ulteriormente elevato l’esperienza, offrendo un’atmosfera autentica che era precedentemente disponibile solo nei casinò fisici.

Le strategie di gioco e la preparazione possono influenzare significativamente le probabilità di vincita, ma è importante mantenere sempre un approccio responsabile. I giocatori dovrebbero dedicare tempo alla ricerca e all’apprendimento delle regole e delle strategie di ciascun gioco per massimizzare il loro divertimento e le loro possibilità di successo. Con questo spirito, i giochi da tavolo online rappresentano una scelta eccellente per chi cerca un’esperienza di gioco avvincente e coinvolgente.

Se stai cercando ulteriori risorse e informazioni sui giochi da tavolo nei casinò online, il nostro sito è una fonte preziosa. Offriamo guide, strategie, recensioni e suggerimenti per aiutarti a navigare nel mondo dei giochi da tavolo online. Con un impegno costante verso la qualità e la responsabilità, siamo qui per supportarti nella tua avventura di gioco.

Transform your experience: navigating payments for custom AI girls securely


As we move into 2026, the world of custom AI girls continues to evolve, becoming increasingly popular for various applications, from companionship to personal assistance. Understanding how to navigate the landscape of customizing and paying for these AI creations is crucial, especially when considering options like shantidate dating for connecting with like-minded individuals. This article will explore secure payment options available for acquiring custom AI girls, ensuring a safe and efficient experience for users.

How custom AI girls are revolutionizing digital interaction

Custom AI girls are reshaping how we interact with technology and each other. These AI companions can be tailored to meet specific preferences, providing users with not just a service, but a personalized experience. From personality traits and appearance to the ability to engage in meaningful conversations, the options are vast. As their capabilities expand, the need for secure payment methods becomes essential to protect users’ personal and financial information during transactions.

This article delves into the significance of payment security while customizing AI girls. With considerations for privacy and data protection, users can enjoy their AI companions with peace of mind. Understanding the payment landscape is vital for anyone looking to invest in AI technology.

Steps to get started with acquiring custom AI girls

Embarking on the journey to acquire a custom AI girl involves several steps that ensure a smooth and secure experience. Below are the fundamental steps to get you started on this path.

  1. Choose Your Platform: Start by selecting a reputable platform that specializes in custom AI girl creation. Look for user reviews and safety features.
  2. Design Your AI: Utilize the platform’s tools to customize your AI girl according to your preferences, ensuring all chosen features align with what you’re seeking.
  3. Create an Account: Register on the platform by providing necessary details. Ensure your password is strong to protect your account.
  4. Verify Your Identity: Complete any verification steps required by the platform, which may include email or phone verification to safeguard transactions.
  5. Choose Payment Method: Review the secure payment options available for transaction completion.
  6. Confirm and Download: Once your payment is processed, confirm your order and download your custom AI girl.
  • Choose from a variety of platforms with solid reputations.
  • Customize features for a personalized experience.
  • Ensure account security through strong passwords and verification.

Practical considerations for payment in AI girl customization

When it comes to acquiring custom AI girls, understanding the various payment methods available is essential. Popular platforms often offer multiple payment options, including credit cards, digital wallets, and cryptocurrency. Each method has its pros and cons, impacting security and transaction speed. For instance, credit card payments are widely accepted and provide buyer protection, while cryptocurrency offers enhanced anonymity for those concerned about privacy.

In addition to choosing a payment method, users should be aware of the associated fees and processing times. Some platforms may impose service fees based on the chosen transaction method. Therefore, reading the fine print is crucial to avoid unexpected costs. Furthermore, opting for platforms with transparent payment policies ensures a better overall experience.

  • Credit cards typically offer buyer protection.
  • Digital wallets like PayPal can speed up transactions.
  • Cryptocurrencies provide enhanced privacy during payment.

Being informed about these details helps streamline the process and ensures that users can focus on enjoying their AI creations rather than worrying about payment issues.

Key benefits of secure payment options for custom AI girls

Choosing secure payment options when purchasing custom AI girls comes with numerous benefits. Ensuring that transactions are safe not only protects personal and financial information but also enhances user experience overall.

  • Enhanced Security: Secure payment methods reduce the risk of fraud and data breaches.
  • Privacy Protection: Options like cryptocurrencies offer anonymity, allowing users to transact discreetly.
  • Quick Resolutions: With established payment systems, any transaction errors can be quickly resolved.
  • Ease of Use: Familiar payment methods make it easier for users to navigate the process.

By prioritizing secure payment options, users can enjoy their custom AI girls with confidence, knowing that their financial safety is taken seriously.

Trust and security in AI girl transactions

In the realm of custom AI girls, trust and security are paramount. Users should always look for platforms that implement robust security measures, such as encryption and regular security audits. Platforms that adhere to these practices not only protect users’ data but also build a reputation for reliability in an industry that is still evolving.

Furthermore, user feedback and third-party reviews can provide insight into the trustworthiness of a platform. Engaging with communities that focus on custom AI girls can also guide users toward platforms with proven track records of secure transactions.

  • Look for SSL encryption on payment pages.
  • Check for user reviews and testimonials.
  • Use platforms known for their commitment to data protection.

Why choose secure payment platforms for custom AI girls

In summary, opting for secure payment platforms when acquiring custom AI girls ensures a safe and enjoyable experience. The ability to customize a digital companion while maintaining privacy and security is invaluable in today’s digital landscape. By taking the necessary precautions regarding payment methods and trusting established platforms, users can enhance their interaction with AI technology.

As AI girls become more integrated into personal and professional lives, making informed decisions about customization and payment will pave the way for a rewarding journey into the future of digital companionship. Prioritizing secure transactions not only protects users but enhances overall satisfaction with their custom AI experiences.

Casino etikett Mit érdemes tudni a játék előtt

Casino etikett Mit érdemes tudni a játék előtt

A kaszinói etikett alapjai

A kaszinók világa nem csupán a szerencséről szól; a megfelelő etikett is elengedhetetlen része a játékélménynek. Az etikett betartása segít megteremteni a barátságos légkört, ahol mindenki jól érzi magát. Fontos, hogy a játékosok tiszteletben tartsák egymást, hiszen a kaszinóban való viselkedés nem csupán a saját érdekeiket, hanem a körülöttük lévőkét is befolyásolja.

A kaszinóban történő viselkedés magában foglalja a megfelelő öltözködést is. Bár sok helyen a szabadidős öltözet is megengedett, egy elegánsabb megjelenés mindig előnyös lehet. A formális események vagy magas tétekkel zajló játékok esetén a diszkrét, de ízléses öltözék javasolt. Ez nemcsak a tisztelet jele, hanem növeli a játékos önbizalmát is.

JumboSpin casino

Továbbá, a játékosoknak tisztában kell lenniük a játék folyamataival és a szabályokkal. A kezdők számára hasznos lehet, ha egy kis időt szánnak arra, hogy megismerjék az adott játék szabályait, mielőtt leülnek játszani. Ez segít elkerülni a feszültséget, és hozzájárul a zökkenőmentes játékélményhez.

Viselkedés az asztalnál

A játék során különösen fontos a megfelelő viselkedés. Az asztalok körüli légkör feszültsége nagyban befolyásolja a játékélményt. A játékosoknak kerülniük kell a hangos beszélgetést vagy az asztalnál való vitatkozást, hiszen ezek zavarhatják a többi játékost. A megértő és együttműködő hozzáállás sokkal élvezetesebbé teszi a játékot mindenki számára.

A kártyajátékoknál és a pókerben elengedhetetlen, hogy a játékosok figyelmesek legyenek az ellenfeleikre. A blöffölés és a taktikázás része a játéknak, azonban a tiszteletteljes hozzáállás megőrzése mindenképpen ajánlott. A túlzott gúnyolódás vagy sértések nemcsak a játék hangulatát rontják, hanem a játékosok közötti kapcsolatokat is megmérgezhetik.

Egy másik fontos szempont, hogy ne zaklassuk a krupiékat. A krupiék szakmai játékosok, akik az asztal irányításáért felelnek, és mindenki számára elérhető segítőkészséggel állnak rendelkezésre. Amennyiben kérdésünk van, érdemes udvariasan, de határozottan feltenni azt, anélkül, hogy zavarba hoznánk őket a folyamatos faggatással.

Ital és étkezés etikett

A kaszinóban való ivás sok játékos számára szórakoztató részét képezi az estének, azonban fontos, hogy ezt mértékkel tegyük. A túlzott alkoholfogyasztás nemcsak a játékra, hanem a viselkedésünkre is negatív hatással lehet. Érdemes tudatosan figyelni arra, hogy ne fogyasszunk el több italt, mint amit elbírunk, hiszen a cél a szórakozás, nem a szégyen.

Az italok rendelésekor fontos, hogy a pincér figyelmét udvariasan kérjük fel. A kaszinókban gyakran több vendég is várakozik, ezért a türelem és a tisztelet megőrzése kulcsfontosságú. Ne felejtsük el, hogy a szervizdíj is része a kaszinói etikettnek, így a pincérek munkáját is érdemes megbecsülni.

Az étkezés etikettje szintén elengedhetetlen. Amennyiben az asztalnál étkezünk, tartsuk tiszteletben a többiek étkezési szokásait. Ne zajongjunk és ne beszéljünk tele szájjal, hiszen ez nemcsak zavaró, hanem a kultúrált étkezés normáival is ellentétes. Az ételek élvezete során figyeljünk arra, hogy ne lépjünk túl a jó ízlés határain, és ne zavarjuk meg a játék menetét.

A játékok megértése és tiszteletben tartása

Az egyik legfontosabb aspektusa a kaszinói etikettnek a játékok megértése. Mielőtt leülnénk játszani, érdemes áttekinteni a kiválasztott játék szabályait. Ez különösen fontos a bonyolultabb játékok, mint a póker vagy a blackjack esetén, ahol a stratégiák és a döntések alapvetően befolyásolják az eredményt. A tudás segít abban, hogy a játék során magabiztosabbak legyünk.

Továbbá, a játék során tiszteletben kell tartanunk a játékosok és a krupiék döntéseit is. Ne próbáljunk beavatkozni mások játékába, hiszen mindenki saját stratégiával és megközelítéssel játszik. A játékhoz való hozzáállásunk tükrözi a tiszteletünket a többiek iránt, és hozzájárul az általános légkörhöz.

Ne felejtsük el, hogy a kaszinó nem csupán a nyerésről szól, hanem a szórakozásról is. Élvezzük a játékot, és ne vegyük túl komolyan a vereségeinket. A pozitív hozzáállás nemcsak saját élményünket javítja, hanem a körülöttünk lévő játékosokét is.

A JumboSpin casino bemutatása

A egy modern online kaszinó, amely a magyar játékosok számára kínál szórakoztató és biztonságos játékkörnyezetet. Az oldal széles választékot kínál a nyerőgépek, élő játékok és sportfogadások terén, így mindenki megtalálhatja a számára legmegfelelőbb opciót. Az új felhasználók számára különböző üdvözlő bónuszok érhetők el, amelyek vonzóbbá teszik a kezdést.

Az oldal könnyen navigálható felülete lehetővé teszi, hogy a kezdők és a tapasztalt játékosok is egyszerűen eligibilitassanak a különböző játékok között. A demó lehetőségek révén a játékosok kockázat nélkül próbálhatják ki az egyes játékokat, mielőtt valódi pénzben játszanának. Ez különösen hasznos azok számára, akik még nem jártasak a kaszinók világában.

Összességében a nemcsak a szórakozás, hanem a biztonságos játékélmény iránt is elkötelezett. Az oldal célja, hogy egy kellemes és élvezetes környezetet biztosítson minden látogató számára, ahol a játékosok jól érezhetik magukat, és zökkenőmentesen élvezhetik a játékokat. Az etikett betartása és a megfelelő viselkedés hozzájárul a kaszinó által nyújtott élmény fokozásához.

×